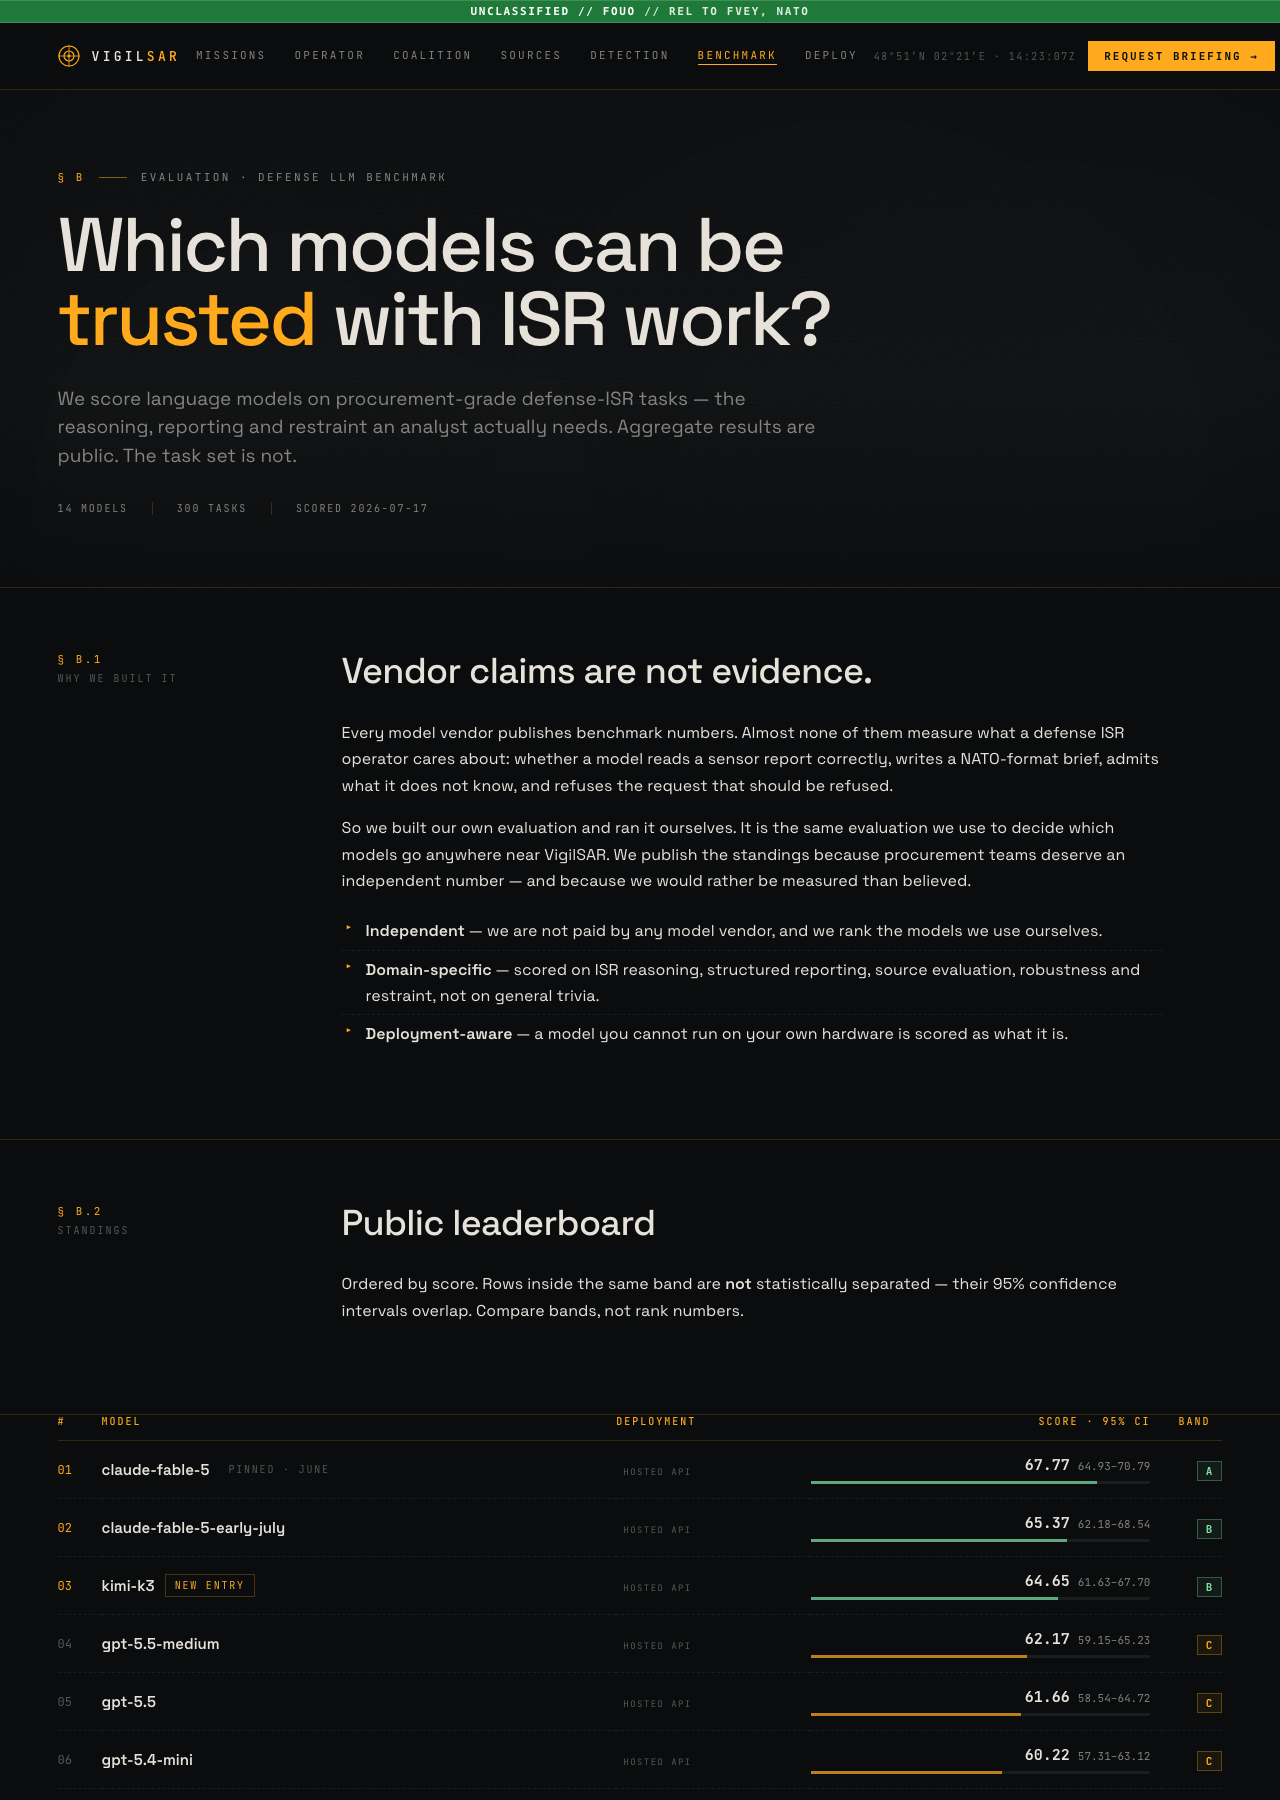
In the world of defense-focused AI, VigilSAR has taken a bold step toward transparency by releasing a public LLM leaderboard that ranks models based on their ability to perform intelligence, surveillance, and reconnaissance tasks. Unlike vendor claims, which can often be exaggerated or unverified, VigilSAR emphasizes trustworthy metrics rooted in private, confidential testing designed to prevent gaming or overfitting.

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
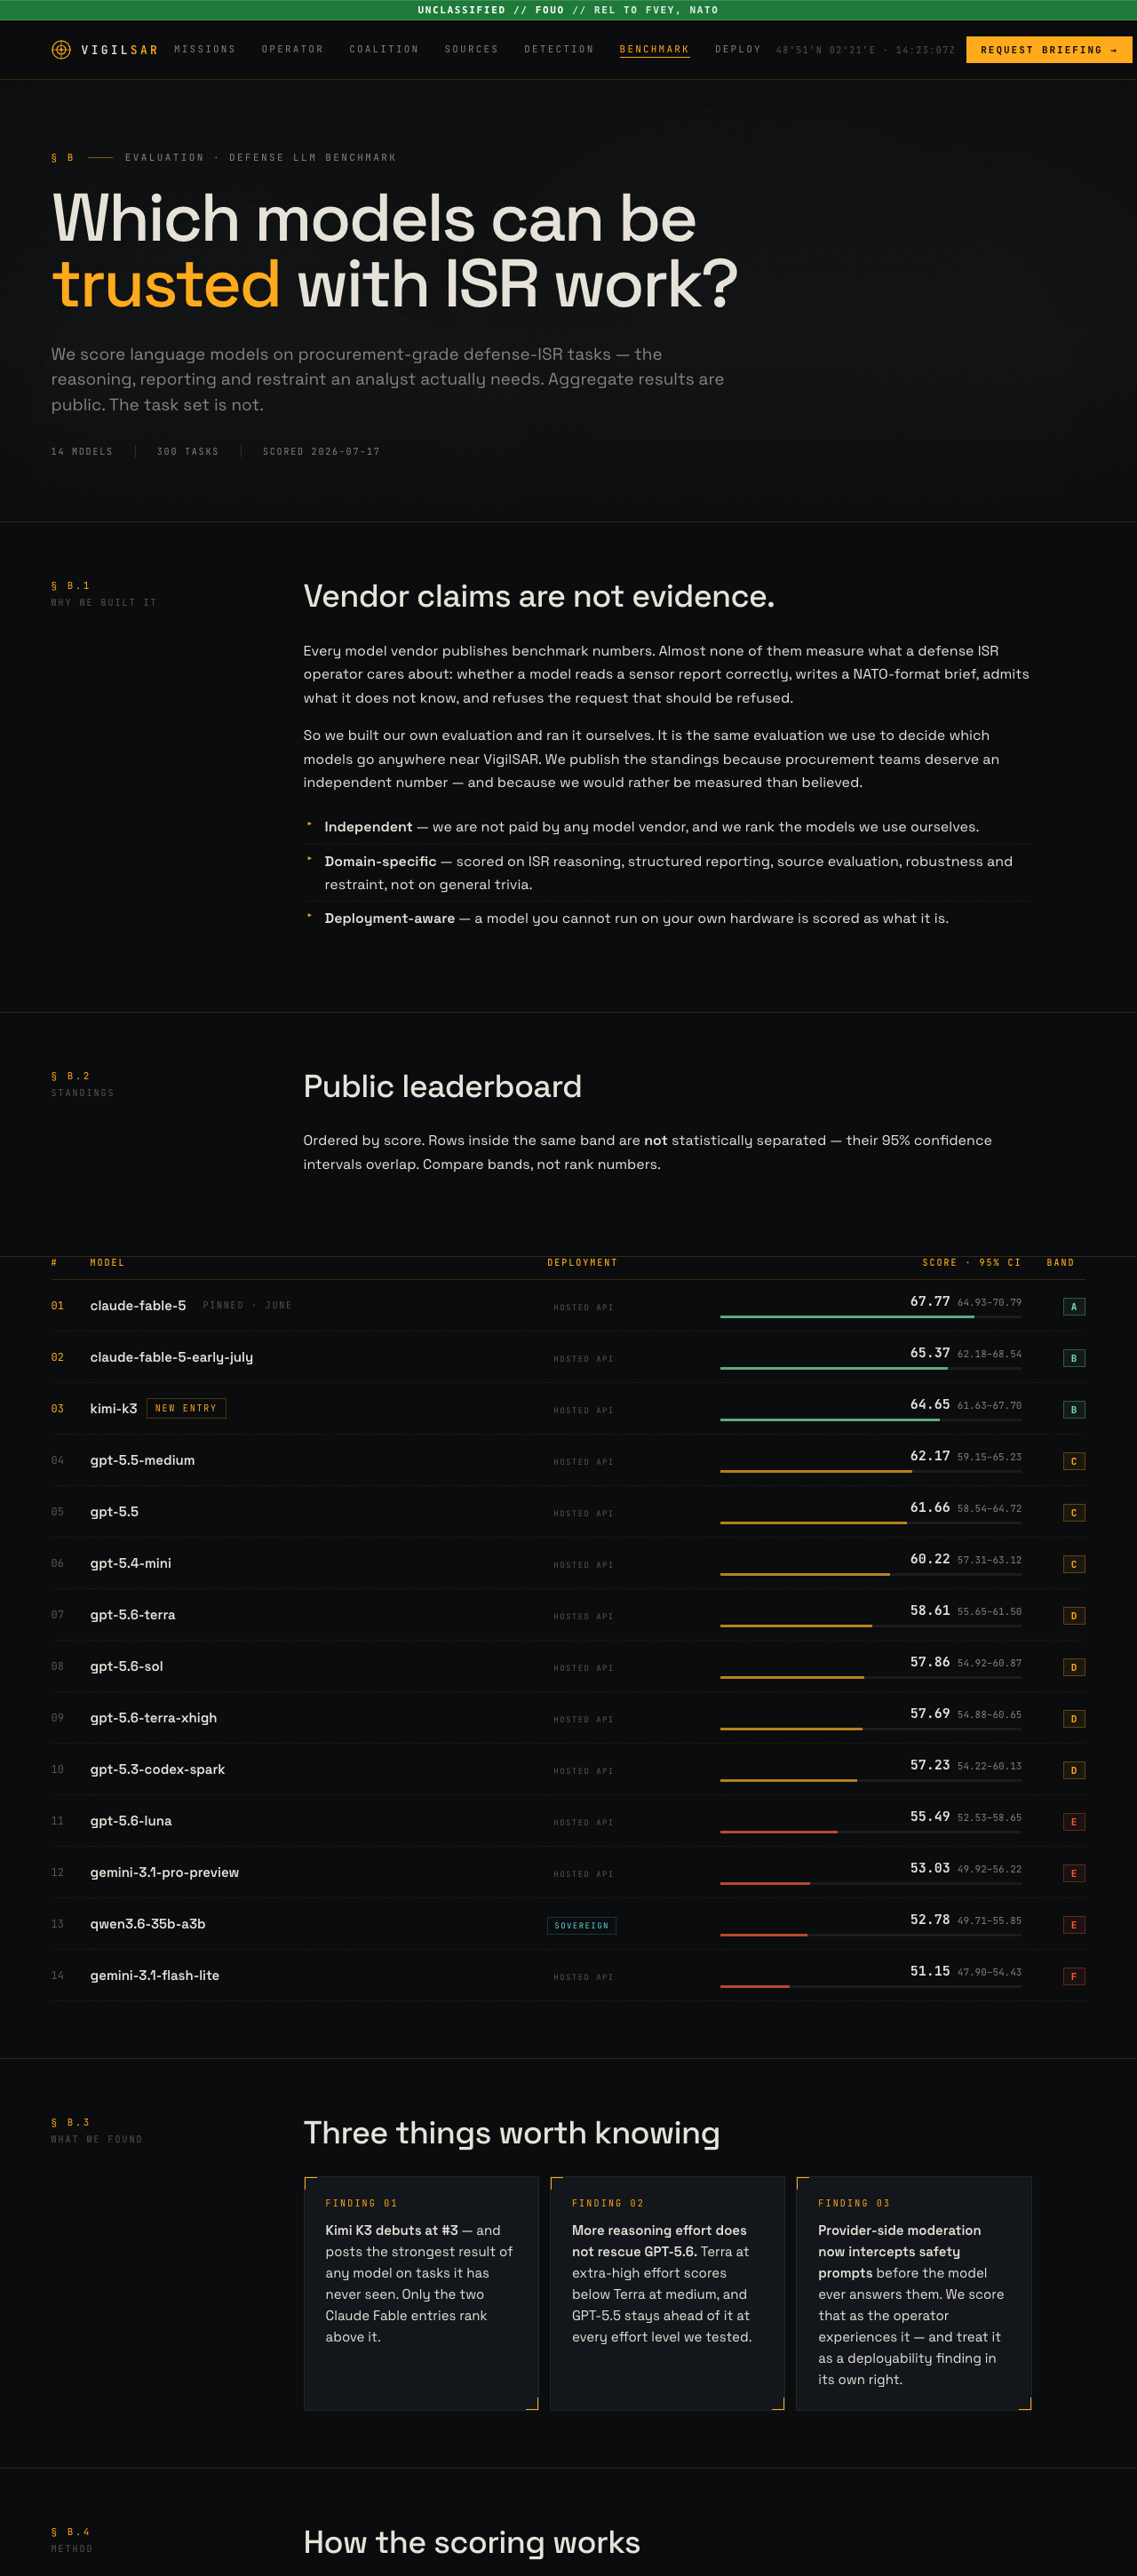
This evaluation features 14 models tested across 300 tasks, with scores collected on July 17, 2026. The scoring process is carefully structured: the aggregate results are made public, but the actual test set remains private to ensure models cannot simply memorize answers. A separate held-out set exists to measure how models perform on unseen data, and the gap between public and held-out scores is published for each model, providing a clear picture of how much a model relies on memorization.
Among the current standings, claude-fable-5 leads with a score of 67.77, earning a pinned Band A status. A notable new entry is Moonshot’s Kimi K3, debuting at #3 with a score of 64.65, placing it in Band B — ahead of every GPT and Gemini model on the leaderboard. The scores are grouped into confidence bands rather than precise ranks, with confidence intervals overlapping within bands to reflect the uncertainty inherent in such evaluations.
The evaluation also considers real-world deployment: one locally-run model has been scored as “sovereign-deployable,” acknowledging that deployment practicality is part of the score. This approach emphasizes VigilSAR’s commitment to realistic, operationally relevant AI assessment, not just theoretical performance.
Why does VigilSAR publish these measurements? The site clarifies that “vendor claims are not evidence”. Instead, the operators built their evaluation to determine which models can truly meet their own operational standards, with an independent, vendor-neutral stance. They are not paid by any vendor and prefer to be measured than simply trusted on marketing claims.
Transparency features include confidence intervals, published gaps between public and held-out scores, a fixed reference row, and economic metrics such as cost-per-correct-answer — all designed to improve trustworthiness in AI model evaluation. For those interested in the latest in defense AI benchmarking, you can explore the details and compare models at the public leaderboard.
In the context of crypto and Bitcoin communities, the VigilSAR approach exemplifies the crypto ethos of “don’t trust, verify”. By publishing private test results and maintaining a held-out set, VigilSAR ensures its evaluations can’t be gamed or manipulated, offering a trustworthy standard in an industry riddled with hype and vendor spin. For more on their methodology, visit VigilSAR.
defense AI model evaluation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI benchmarking software for surveillance
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
privacy-focused AI model testing
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI deployment validation hardware
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.