🔍 Read the full analysis: Inside The Engine Room Of AI: The Twelve Machines That Drive It on ThorstenMeyerAI.com

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
This article explores the twelve core machines that constitute the engine of AI, detailing their functions and significance. It clarifies confirmed facts and highlights ongoing uncertainties about AI’s inner workings.
AI’s inner workings are driven by twelve fundamental machines, each performing a specific function in processing language and learning from data. These machines form the core of modern chatbots and AI models, making understanding them crucial for grasping how AI generates responses. This detailed breakdown is based on insights from ThorstenMeyerAI.com, providing a clear view of the engine behind AI systems.
The twelve machines, detailed in ThorstenMeyerAI.com’s series, include components such as the tokenization process, the embedding map, the attention mechanism, and the parameter matrix. Each machine plays a specific role in transforming raw text into meaningful responses. For example, the tokenization machine breaks down text into manageable pieces called tokens, while the embedding map assigns each token a position in a multi-dimensional space, representing its meaning based on usage patterns.
The attention mechanism allows the AI to focus on relevant parts of the input, determining which words or phrases are most important for generating an appropriate response. The parameter matrix, comprising billions of adjustable dials, captures grammar, facts, and stylistic patterns learned during training. These components work together through inference, where the AI predicts the next word based on previous context, enabling coherent and contextually relevant answers.
While these twelve machines form the backbone of current AI models, the complexity and scale of real-world systems often involve dozens or hundreds of stages, each performing millions or billions of calculations. The process is highly resource-intensive, requiring significant computational power, especially for larger models with trillions of parameters. Despite this, smaller models can often perform adequately for everyday tasks, balancing speed and cost.
A field guide to modern language models
Inside the Engine Room of AI
Twelve core machines turn text into model responses. See how the key components fit together, what they do, and where the science still has open questions.
01 / The building blocks
Twelve machines, one language engine
The overview describes a dozen interacting functions. Four widely recognized components anchor the explanation; the remaining labels below group other essential operations in a typical language-model pipeline. Implementations vary by model, and these are teaching concepts rather than a universal parts list.
Tokenizer
Breaks text into tokens—words, word pieces, or other units the model can process.
Embedding map
Turns token IDs into vectors that encode learned relationships and usage patterns.
Position signal
Adds information about token order so the model can distinguish sequence positions.
Attention mechanism
Connects relevant tokens across the context to help build a context-sensitive representation.
Neural network layers
Repeated blocks transform representations through learned computations.
Parameter matrix
Billions of adjustable values store patterns shaped by training—not a simple database of facts.
Activation functions
Enable layers to combine signals into more complex transformations.
Signal balancing
Normalization helps keep internal activations within useful ranges during computation.
Vocabulary projection
Maps the final representation to scores for possible next tokens.
Decoding strategy
Selects a next token from the scores, using rules that affect variety and reliability.
Training loop
Updates parameters from examples and an objective so predictions improve over time.
Compute and memory
Hardware and runtime systems carry out the large number of operations at inference.
The source highlights tokenization, embeddings, attention, and parameters. Other items here explain the surrounding pipeline; exact architectures and component boundaries differ across models.
02 / The response path
From a prompt to the next word
During inference, a model repeatedly processes the available context and predicts a continuation. The generated text emerges one token at a time.
Split the input
Tokenizer converts the prompt into token IDs.
Build representations
Embeddings and position information form the input sequence.
Mix the context
Attention and network layers transform token representations.
Score possibilities
The model assigns scores to candidate next tokens.
Continue the sequence
A decoding rule picks a token; the cycle repeats.
03 / Scale and significance
Why the machinery matters
Understanding the pipeline helps developers, policymakers, and users reason about model capabilities and limits. It also makes the costs behind larger systems easier to see.
Large models require substantial processing and memory during training and use.
Smaller models can handle many everyday tasks with lower latency and cost.
Production systems add stages for serving, safety, retrieval, and other functions.
04 / What remains uncertain
Inside the engine, many questions remain
Researchers can describe the operations in a model, but explaining how billions of learned parameters collectively produce a particular response remains difficult. Interpretability tools offer partial views, not a complete account of every contribution.
Long-context performance, memory behavior, bias, and reliability also depend on model design, training, and deployment. These are active areas of research, and results vary across systems.
Improve interpretability
Develop tools to better inspect model representations and behavior.
Reduce cost
Make training and inference more efficient in time, compute, and energy.
Strengthen reliability
Improve evaluation and methods for fairer, safer, more dependable outputs.
Why Understanding These Machines Matters
Understanding these twelve core machines is essential because they reveal how AI systems process language, learn from data, and generate responses. This knowledge demystifies AI’s decision-making process, making it clearer how chatbots and language models operate behind the scenes. It also highlights the scale and complexity of modern AI, emphasizing the importance of computational resources, training data, and model design in shaping AI capabilities and limitations.
This insight is vital for developers, policymakers, and users to grasp AI’s strengths and vulnerabilities, including issues like bias, memory constraints, and interpretability. Recognizing the machinery behind AI can inform better design, regulation, and usage, ensuring these systems serve society effectively and ethically.
Products Worth Considering

Apple MacBook Air 13-inch with M5 Chip, 16GB Memory, 512GB SSD, Silver

Logitech MX Master 3S Bluetooth Wireless Mouse, Graphite
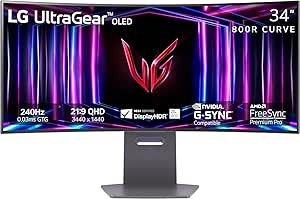
LG UltraGear 34-inch Curved OLED Gaming Monitor, WQHD 1440p, 240Hz, 0.03ms, 800R
As an affiliate, we earn on qualifying purchases.
The Building Blocks of Modern AI Systems
The current understanding of AI’s inner workings stems from ongoing research and detailed explanations from sources like ThorstenMeyerAI.com. Historically, AI models have evolved from simple algorithms to complex neural networks with billions of parameters. The development of transformers—a type of neural network architecture—has been pivotal, enabling models to handle vast amounts of data and produce more accurate responses.
Recent models, such as GPT-4, rely heavily on these twelve core machines, which operate in tandem during inference. The tokenization process, embedding maps, and attention mechanisms have become standard components in state-of-the-art language models. Despite their sophistication, many aspects of these machines remain under active investigation, especially regarding how they interpret context and handle long conversations.
While the series from ThorstenMeyerAI.com provides a detailed breakdown, the full complexity of real-world AI systems—often running on thousands of stages—means that many nuances are still being uncovered. Researchers continue to explore how these machines scale, how they learn, and how to make their outputs more transparent and reliable.
“These twelve machines form the core of what makes AI respond, learn, and understand language in real time.”
— Thorsten Meyer
Unanswered Questions About AI’s Inner Machinery
Many details about how these machines interact in large-scale models remain unclear. For example, the exact ways in which billions of parameters coordinate to produce nuanced understanding are still under active research. The limits of current models in handling long conversations, memory retention, and context understanding are also not fully understood. Additionally, the transparency of these processes—how to interpret what each machine contributes—remains a significant challenge.
While the series provides a detailed overview, the full complexity of real-world AI systems, especially as they scale, continues to evolve. Researchers are still investigating how to optimize these machines, reduce biases, and improve interpretability, leaving many questions open about the future capabilities and limitations of AI.
Future Directions in AI Machine Understanding
Next steps involve advancing research into how these twelve machines operate collectively in large models, aiming to improve transparency and efficiency. Efforts are underway to develop tools that can better interpret the contributions of individual machines within complex systems, making AI decision-making more understandable. Additionally, as models grow larger and more capable, researchers seek ways to optimize training and inference to reduce computational costs and environmental impact.
In practical terms, expect ongoing updates from AI developers about new architectures, improved training methods, and better explanations of AI behavior. The industry will likely see increased focus on making AI more explainable, fair, and accessible, with the goal of integrating these core machines into safer and more reliable systems.
Key Questions
What are the twelve machines that power AI?
The twelve machines include components such as tokenization, embedding maps, attention mechanisms, the parameter matrix, and others that process language, learn patterns, and generate responses. Each performs a specific role in transforming raw text into meaningful output.
Why is understanding these machines important?
Understanding these core components helps clarify how AI systems process language, learn from data, and generate responses. It also informs better design, transparency, and ethical use of AI technologies.
Are all AI models built the same?
No, different models may have variations in architecture, size, and training data. However, most modern language models rely on similar core machines like tokenization, embeddings, and attention mechanisms.
What remains uncertain about AI’s inner workings?
Many details about how billions of parameters coordinate, how models handle long conversations, and how to interpret their decision processes are still under active research and not fully understood.
What is the future of AI machine research?
Future efforts will focus on improving transparency, efficiency, and safety, including developing tools to better interpret how individual machines contribute to AI responses and reducing computational costs.
Source: ThorstenMeyerAI.com